The Making of PD12M: Dataset Curation - by Laura Exline
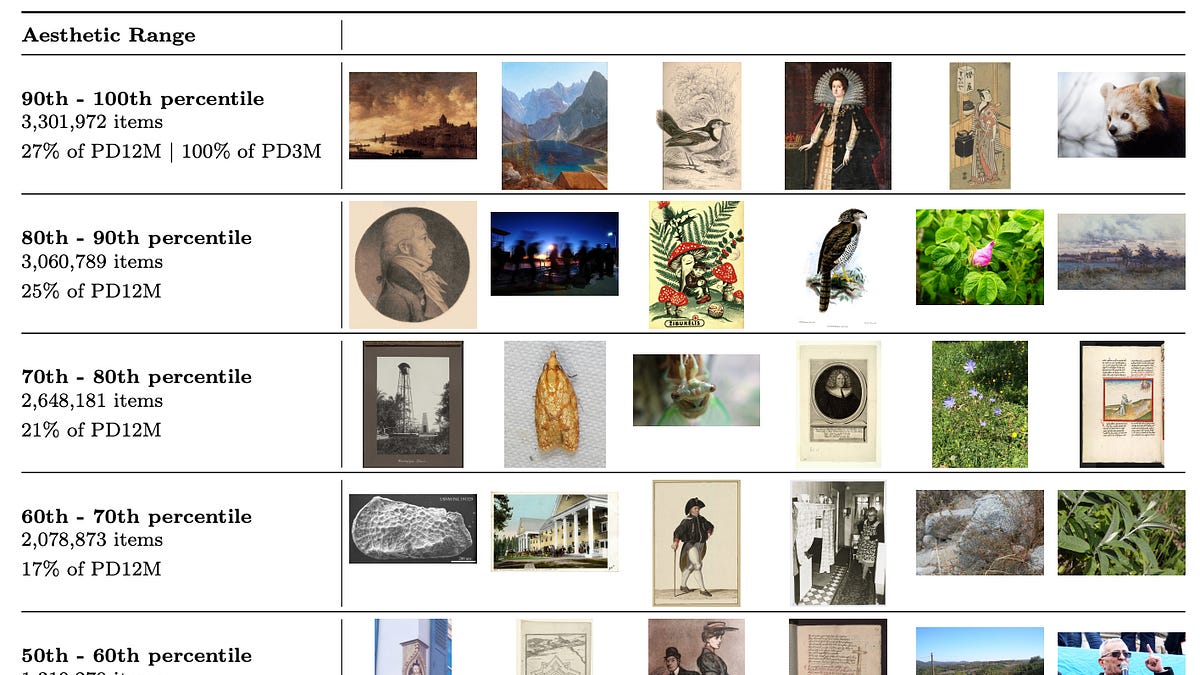
AI summary of the linked articlePD12M, a 12.4 million image-caption dataset of public domain and CC0 images, was curated from about 38 million images on Source.Plus, according to Laura Exline's post on its curation process. The team filtered out 8.7 million document scans, set a minimum resolution of 256x256 pixels, and excluded works with an NSFW score above 0.5. Using a custom aesthetic model, they dropped the bottom 50% of images by score to match the size of CC12M, and the bottom 90% to match CC3M's 3.3 million. |
Comments No comments yetWhat caught your eye? Start the discussion. |